Lifecycle
to Production
Workflows
AI ENGINEER
TUESDAYS & THURSDAYS
6 PM PT / 9 PM ET
9 FEB 2027 - 15 APR 2027
DURATION:
10 WEEKS
TUESDAYS & THURSDAYS
6 PM PT / 9 PM ET
Build the systems behind the intelligence.
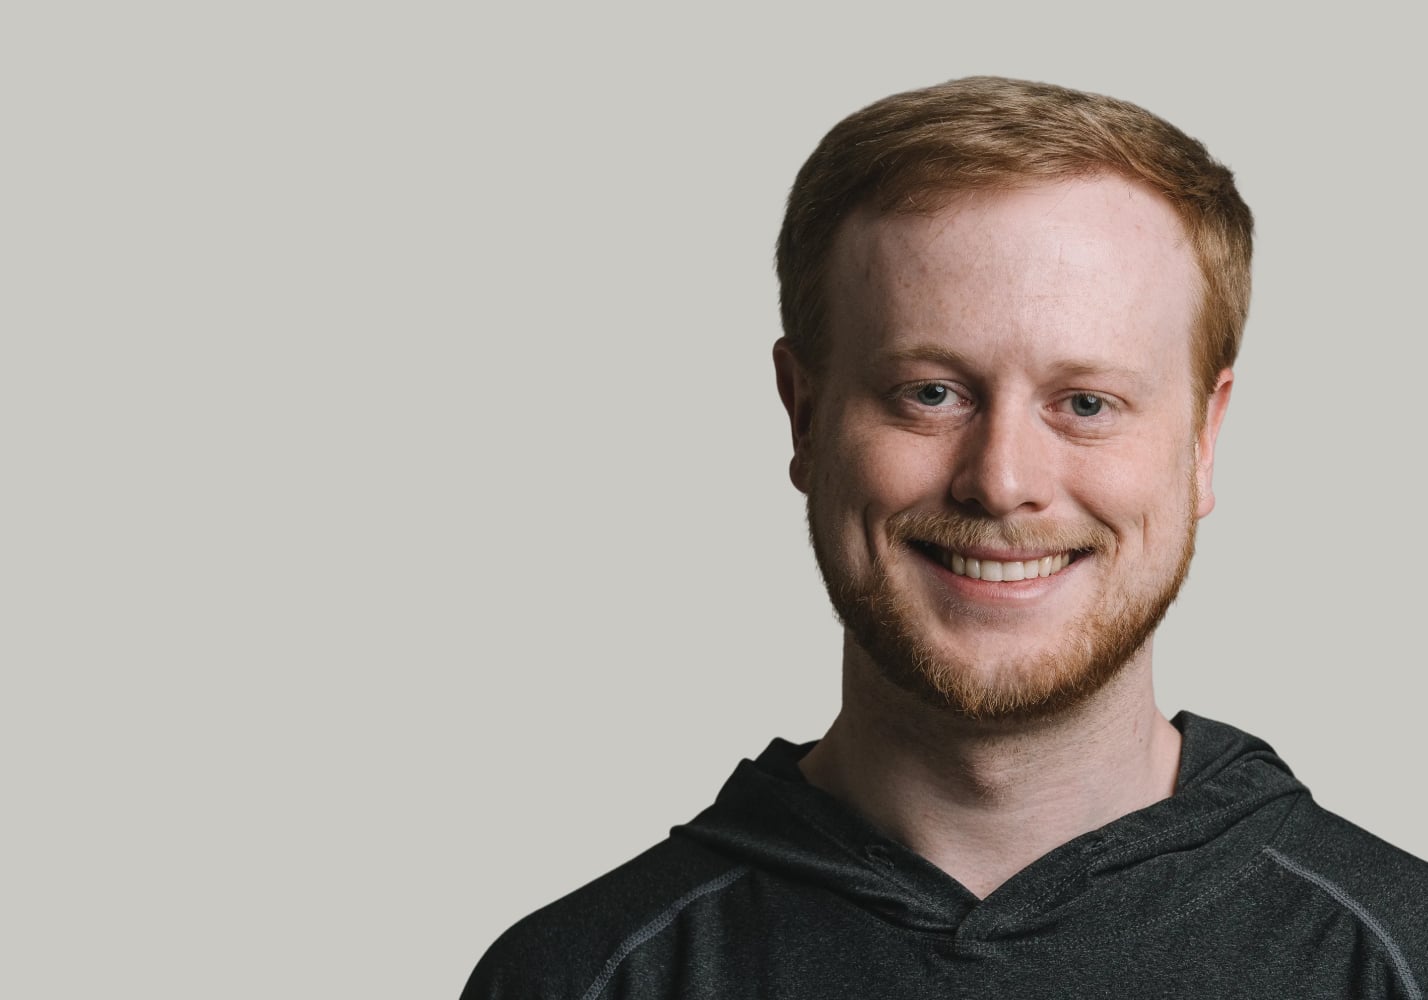
Tanner Gilligan, Principal AI Engineer at Microsoft, teaches you how data, models, infrastructure, and MLOps come together to create scalable AI products that deliver real value.
THIS COURSE IS FOR YOU, IF...
-
YOU ARE A SOFTWARE DEVELOPER
You can build APIs, ship features, and write production-grade code. But when a model hallucinates, underperforms, or behaves unpredictably, debugging gets murky fast. Weβll demystify modern AI systems, showing you how models, data, prompts, RAG pipelines, and deployment workflows fit together. Turn AI from a black box into another part of your engineering toolkit.
-
YOU ARE A DATA SCIENTIST
Your models perform great in notebooks, but getting them into production is a different challenge altogether. This AI engineer course bridges the gap between experimentation and deployment, helping you transform prototypes into scalable, maintainable AI systems. Learn how real-world AI products are built, monitored, versioned, and improved long after the first model is trained.
-
YOU ARE AN MLOPS OR CLOUD PROFESSIONAL
You know infrastructure, automation, and deployment, but AI workloads play by their own rules. Gain a deeper understanding of the systems behind modern AI applications: vector databases, model registries, observability, drift detection, and continuous training pipelines. Learn how to connect infrastructure, data, and models into end-to-end AI solutions that perform reliably in production.
Our students work in 1600+ companies worldwide
- Leads AI engineering initiatives as Principal AI Engineer at Microsoft, designing and deploying production-scale AI systems that solve complex business and technical challenges
- Earned both a BS and MS in Artificial Intelligence from Stanford University in just four years, building a deep foundation in AI/ML & data science
- Invented and patented AI technologies, holding 12 patents focused on anomaly detection and time-series analysis
- Co-founded an AI startup, gaining hands-on experience transforming emerging technologies into practical products
- Brings more than a decade of full-time AI experience, complemented by 5+ years of AI consulting across industries
- Architected and delivered a wide range of AI solutions, including recommendation engines, natural language-to-SQL systems, taxonomy generation platforms, seasonality detection models, RAG databases, and malicious-request classification systems
- Role definitions (AI Engineer vs. ML Engineer vs. Data Scientist)
- Go/No-Go framework for when (not) to use AI
- Problem mapping (business problem β ML problem type)
- Capstone kickoff
- Usage of AI in course
- Env setup
- Data contracts and source requirements
- Internal and public data sources, permissions, and provenance
- Sampling strategies and targeted acquisition
- Human, paid, semi-supervised, and LLM-assisted labeling
- Synthetic data methods, realism, and safety
- Dataset context, row grain, and early label trust checks
- Data inspection and profiling (e.g. ydata-profiling, Sweetviz)
- Data quality, cleaning, and auditability
- Association, distributions, anomalies, representativeness, drift, and seasonality
- Interpreting findings and making a data-readiness recommendation
- Train/val/test split strategies (e.g. stratified, time-based, grouped, cluster-aware)
- Rebalancing the training set (e.g. oversampling, undersampling, weighted learning)
- Leakage, sensitive fields, and dataset versioning
- Cross-validation for small datasets
- Operational data validation (data contracts, record checks, monitoring)
Assignment #1: Create + evaluation task dataset
Deadline: 1 week
- Baseline levels (random, constant, rule-based, similarity-based, trained models)
- Traditional ML models (logistic regression, tree-based, etc.)
- Feature engineering for numeric, categorical, text, datetime, and mixed data
- Feature selection, hashing, and dimensionality reduction
- Matching preprocessing and feature representations to model families
- Confusion matrices, positive-class definition, and error costs
- Classification metrics (Accuracy, Precision, Recall/TPR, TNR, FPR, FNR, F1, ROC-AUC, PR-AUC)
- Metric tradeoffs, threshold policies, deferral, and calibration
- Choosing primary, secondary, guardrail, and diagnostic metrics for classification problems
- Standardized comparison, slices, uncertainty, and practical significance
- Evaluation reports and offline-to-online validation
Assignment #2: Create + evaluation baseline model
Deadline: 1 week
- Numeric prediction metrics (MAE, RMSE, RΒ², tolerance bands, error percentiles, residual patterns)
- Ranking, retrieval, and recommendation metrics (precision@k, recall@k, hit rate, MRR, NDCG)
- Clustering evaluation (silhouette, Davies-Bouldin, ARI, NMI, stability, human review)
- Anomaly-detection metrics (class-specific quality, PR-AUC/ROC-AUC, investigation queues, alert budgets)
- Forecasting evaluation (horizons, time-aware baselines, prediction intervals, rolling backtests)
- Improvement loop (baseline β evaluation β error analysis β targeted change β re-evaluation)
- Sampling predictions, establishing trusted references, and identifying failures
- Failure patterns, data slices, pipeline checks, and model-specific diagnosis
- Testing whether gains are meaningful and free of unacceptable regressions
- Hyperparameter tuning (e.g. Optuna, Bayesian optimization)
- Overfitting detection, mitigation, and stopping criteria (diminishing returns, validation plateaus)
Assignment #3: Analysis baseline model errors + iterate
Deadline: 1 week
- LLM basics (tokens, context windows, attention, stateless requests)
- Model choice, reasoning models, and cost/latency tradeoffs
- LLM requests, inference parameters, and token-cost modeling
- Prompt patterns (zero-shot, few-shot, decomposition, step-by-step prompting)
- Data boundaries, prompt injection, structured outputs, and validation
- LLM quality criteria, uncertainty policies, and evaluation-set design
- Deterministic checks, rubrics, human review, pairwise comparison, and LLM-as-judge
- LLM error analysis and the optimization hierarchy (context, instructions, model, process)
- When to fine-tune vs. prompt, RAG, tools, or workflow changes
- Fine-tuning types, datasets, evaluation, tradeoffs, and parameter-efficient methods (e.g. LoRA, QLoRA)
Assignment #4: Develop and iterate on prompt for LLM-based model
Deadline: 1 week
- Direct lookup vs. RAG and retrieval approaches (vector, keyword, structured, graph)
- RAG architecture (Index β Query Transform β Retrieve β Rerank β Generate)
- Vector databases (e.g. Chroma, Pinecone, pgvector)
- Documents, chunking, embeddings, index freshness, and source maintenance
- Retrieval quality, grounded generation, citations, and abstention
- RAG evaluation and failure diagnosis (retriever, generator, citation, end-to-end)
- Memory approaches (recent context, summaries, structured profiles, vector memory)
- Bounded workflow patterns (chaining, routing, parallel steps, draft-and-review)
- Tool/function calling, tool schemas, and tool validation
- Tool integration (e.g. Model Context Protocol)
- Context management (summarization, compression, session state, context budgeting)
- Guardrails and threat modeling (input/output validation, permissions, prompt injection, PII, hallucination mitigation)
- Production efficiency and reliability (routing, caching, fallbacks, retries, rate limits, tracing)
- Safe failure handling, workflow evaluation, isolation, and versioned application artifacts
Assignment #5: Build and iterate on RAG subsystem
Deadline: 1 week
- Levels of autonomy and agentic architecture (loop, tools, state, evidence, stopping rules)
- Planning patterns, bounded workflows, and task budgets
- Failure recovery, compounding errors, escalation, and human oversight
- Prompt injection, action permissions, reversibility, and approval boundaries
- Multi-agent relationships, coordination, shared state, and handoffs
- Component, orchestration, and final-output evaluation
- Deployment shapes for traditional ML, self-hosted LLMs, and agentic systems
- Model artifacts, serving applications, and inference servers
- Production Dockerfiles, images, runtime resources, and persistent storage
- Docker Compose for multi-service AI systems, networking, dependencies, and health
- Kubernetes concepts (Pods, Deployments, Jobs, Services, resources, volumes, probes)
Assignment #6: Deploy model + simple UI via Docker
Deadline: 1 week
- Infrastructure provisioning, environments, and staging/production parity
- Registries, coordinated artifacts, compatibility contracts, and release manifests
- Runtime configuration, secrets, service identities, RBAC, and least privilege
- Application hosting, model serving, and capacity-provisioning choices
- Deployment strategies (rolling, blue/green, canary, shadow, rollback)
- CI/CD release controls, readiness gates, auditability, and separation of duties
- Infrastructure, application, security, model-quality, data, and business monitoring
- Observability and tracing (latency, throughput, errors, retries, cost, version context)
- Feedback loops, delayed labels, proxy signals, and continuous evaluation
- Data contracts, training-serving skew, and data/feature/label/concept drift
- Drift detection and comparison windows (e.g. PSI, KS-test, chi-square)
- Actionable alerts, diagnosis, improvement candidates, and retraining triggers
Assignment #7: Add monitoring to docker deployment; interpret results
Deadline: 1 week
- AI impact and failure-mode analysis, including affected parties, consequences, controls, and residual risk
- Contextual fairness analysis, meaningful slices, and the privacy tension created by sensitive attributes
- PII across the AI data lifecycle, including minimization, access, redaction, retention, and deletion
- Data authorization and provenance for confidential, proprietary, licensed, and purpose-limited sources
- Human oversight, transparency, explanation, contestability, correction, and recourse
- Targeted adversarial validation and evidence-based release recommendations
- Learning poorly documented systems top-down with diagrams, repository evidence, and AI-assisted exploration
- Experimentation vs. production engineering, planning uncertain work, and closing the prototype-to-production gap
- Local environments, containers, dev containers, remote VMs, cloud workstations, and GPU VMs
- AI engineering role dimensions, role shapes, work modes, ownership, and production context
- Reading role fit before applying: interpreting ideal-profile requirements, asking mutual-fit questions, and reading the team and process
- AI engineering resumes, evidence-backed work samples, interview stages, and role-specific preparation
- End-to-end integration (data pipeline β model β API β UI β monitoring)
- Peer red-teaming (adversarial inputs, load tests)
- Error handling, graceful degradation
Assignment #8: Finalize project implementation before presentation
Deadline: 1 week
- Live presentations (working UI, business impact slide, GitHub repo)
What our students say
"I really enjoy the format of the course. Lectures with real life examples and an ongoing case study. Also built in 20 minutes at the end of each class for questions is helpful."
"Overall I'm impressed with the level of detail and explanation around particular topics and subjects. There's a real depth to each module which for learning allows the information to stay in your brain."
"The group activities, they allow us to interact and exchange ideas, plus the way it is structured is challenging and mind twisting as we collaborate in different parts of the ideation."
"I enjoyed the structure of the class. I like how we learned about a topic and practiced it in the workshops. Itβs helped me to apply what I learned!"